“Signal Processing in the AI era” was the tagline of this year’s IEEE International Conference on Acoustics, Speech and Signal Processing, taking place in Rhodes, Greece.
In this context, Brent de Weerdt, Xiangyu Yang, Boris Joukovsky, Alex Stergiou and Nikos Deligiannis presented ETRO’s research during poster sessions and oral presentations, with novel ways to process and understand graph, video, and audio data. Nikos Deligiannis chaired a session on Graph Deep Learning, attended the IEEE T-IP Editorial Board Meeting, and had the opportunity to meet with collaborators from the VUB-Duke-Ugent-UCL joint lab.
Featured articles:
- De Weerdt, B. et al., “Designing Transformer Networks for Sparse Recovery of Sequential Data Using Deep Unfolding” (https://ieeexplore.ieee.org/abstract/document/10094712)
- Yang X. et al., “Relevance Propagation through Deep Conditional Random Fields” (https://ieeexplore.ieee.org/abstract/document/10095075)
- Stergiou A. et al., “Play it back: Iterative attention for audio recognition” (https://ieeexplore.ieee.org/abstract/document/10096532, developed at the University of Bristol)

On June 20th 2024 at 16:00, Yangxintong Lyu will defend their PhD entitled “DEEP-LEARNING-BASED MULTI-MODAL FUSION FOR TRAFFIC IMAGE DATA PROCESSING”.
Everybody is invited to attend the presentation in room I.0.02, or digitally via this link.
In recent years, deep-learning-based technologies have significantly developed, which is driven by a large amount of data associated with task-specific labels. Among the various formats used for representing object attributes in computer vision, RGB images stand out as a ubiquitous choice. Their value extends to traffic-related applications, particularly in the realms of autonomous driving and intelligent surveillance systems. By using an autonomous driving system, a car is capable of navigating and operating with diminished human interactions, while traffic conditions can be monitored and analysed by an intelligent system. Essentially, the techniques reduce human error and improve road safety, which significantly impacts our daily life.
Although many visual-based traffic analysis tasks can indeed be effectively solved by leveraging features extracted from a sole RGB channel, certain unresolved challenges persist that introduce extra difficulties under certain situations. First of all, extracting complicated information becomes demanding, especially under erratic lighting conditions, raising a need for auxiliary clues. Secondly, obtaining large-scale accurate labels for challenging tasks remains time-consuming, costly, and arduous. The former prompts exploration into capturing and exploiting additional information such that the objects can be observed from diverse aspects; in contrast, the latter requires either an increase in the volume of available data or the capability to learn from other datasets that already possess perfect labels.
In this thesis, we tackle multi-modal data fusion and data scarcity for intelligent transportation systems. Our first contribution is a novel RGB-Thermal fusion neural network for semantic segmentation. It ensures the segmentation under limited illumination. Our second contribution is a 3D-prior-based framework for monocular vehicle 6D pose estimation. The use of 3D geometry avoids the ill-posed pose prediction from a single camera viewpoint. Thanks to the extra 3D information, our novel method can handle distant and occluded vehicles. The third contribution is a real-world, large-scale vehicle make and model dataset that contains the most popular brands operating in Europe. Moreover, we propose a two-branch deep learning vehicle make and model recognition paradigm to reduce inter-make ambiguity. The last contribution is a weakly supervised vehicle 6D pose estimation paradigm by adapting knowledge built based on a novel synthetic dataset. The dataset includes a large amount of accurate labels for vehicles. By learning from the synthetic dataset, our method allows the significant reduction of expensive real-life vehicle pose annotations.
Comprehensive experimental results reveal that the newly introduced datasets hold significant promise for deep-learning-based processing of traffic image data. Moreover, the proposed methods surpass the existing baselines in the literature. Our research not only yields high-quality scientific publications but also underscores its value across both academic and industrial domains.
On April 25th 2025 at 16:00, Ayman Morsy will defend their PhD entitled “A NOVEL APPROACH TO DEPTH-SENSE IMAGING USING CORRELATION-ASSISTED DIRECT TIME-OF-FLIGHT”.
Everybody is invited to attend the presentation in room I.0.03 or online via this link.
Time-of-flight (ToF) imaging has emerged as a vital technology in machine vision and sensing, expanding into applications such as augmented and virtual reality, gaming, robotics, autonomous driving, autofocus, and facial recognition on smartphones and laptops. ToF technology determines the distance to an object within the detection range by emitting a light source and measuring the time it takes to return. This round-trip time determines the object’s distance, with different sensing technologies employing distinct methods to determine this time.
For ToF applications, developing sensors with high image resolution, low power consumption, and the ability to function reliably in high ambient light conditions is desirable. This dissertation presents the development of a novel single-photon avalanche diode (SPAD)-based pixel called Correlation-Assisted Direct Time-of-Flight (CA-dToF), designed for in-pixel ambient light suppression and characterized by low power consumption and a scalable pixel structure. The CA-dToF pixel uses a laser pulse correlated with two orthogonal sinusoidal signals as input to two switched capacitor channels, which average out detected ambient light while accumulating the laser pulse round-trip time.
To gain insights into CA-dToF pixel operation, both Python simulation and analytical modeling were developed. Two generations of the CA-dToF pixel were developed and characterized, with the second-generation pixel achieving the first operational performance under high ambient light conditions. The two-generation CA-dToF pixel was tested under various lighting conditions and pixel design variations. Additionally, noise sources within the pixel implementation were analyzed, and potential solutions were proposed.
Lucas Moura Santana won the 2022-2023 IEEE SSCS Predoctoral Achievement Award

On October 25th 2024 at 16:00, Yuqing Yang will defend their PhD entitled “CRAFTING EFFECTIVE VISUAL EXPLANATIONS BY ATTRIBUTING THE IMPACT OF DATASETS, ARCHITECTURES AND DATA COMPRESSION TECHNIQUES”.
Everybody is invited to attend the presentation in room D.2.01 or online via this link.
Explainable Artificial Intelligence (XAI) plays an important role in modern AI research, motivated by the desire for transparency and interpretability within AI-driven decision-making. As AI systems become more advanced and complicated, it becomes increasingly important to ensure they are reliable, responsible, and ethical. These imperatives are particularly acute in domains where stakes are high, such as medical diagnostics, autonomous driving, and security frameworks.
In computer vision, XAI aims to provide understandable, straightforward explanations for AI model predictions, allowing users to grasp the decision-making processes of these complex systems. Visualizations such as saliency maps are frequently employed to identify input data regions significantly impacting model predictions, thus enhancing user understanding of AI visual data analysis. However, there are still concerns about the effectiveness of visual explanations, especially regarding their robustness, trustworthiness, and human-friendliness.
Our research aims to advance this field by evaluating how various factors—such as the diversity of datasets, the architecture of models, and techniques for data compression—influence the effectiveness of visual explanations in AI applications. Through thorough analysis and careful refinement, we strive to enhance these explanations, ensuring they are both highly informative and accessible to users in diverse XAI applications.
During our evaluation process, we conduct a detailed investigation using both automatic metrics and subjective evaluation methods to assess the effectiveness of visual explanations thoroughly. Automatic metrics, such as task performance and localization accuracy, provide quantifiable measures of the effectiveness of these explanations in real-world scenarios. For subjective evaluation, we have developed a framework named SNIPPET, which enables a detailed and user-oriented assessment of visual explanations. Additionally, our research explores how these objective metrics correlate with subjective human judgments, aiming to integrate quantitative data with the more nuanced, qualitative feedback from users. Ultimately, our goal is to provide comprehensive insights into the practical aspects of XAI methodologies, particularly focusing on their implementation in the field of computer vision.
Benyameen Keelson and Pieter Boonen sucessfully finished the LifeTech.brussels MedTech accelerator with their startup projects PADFLOW en KARMA.
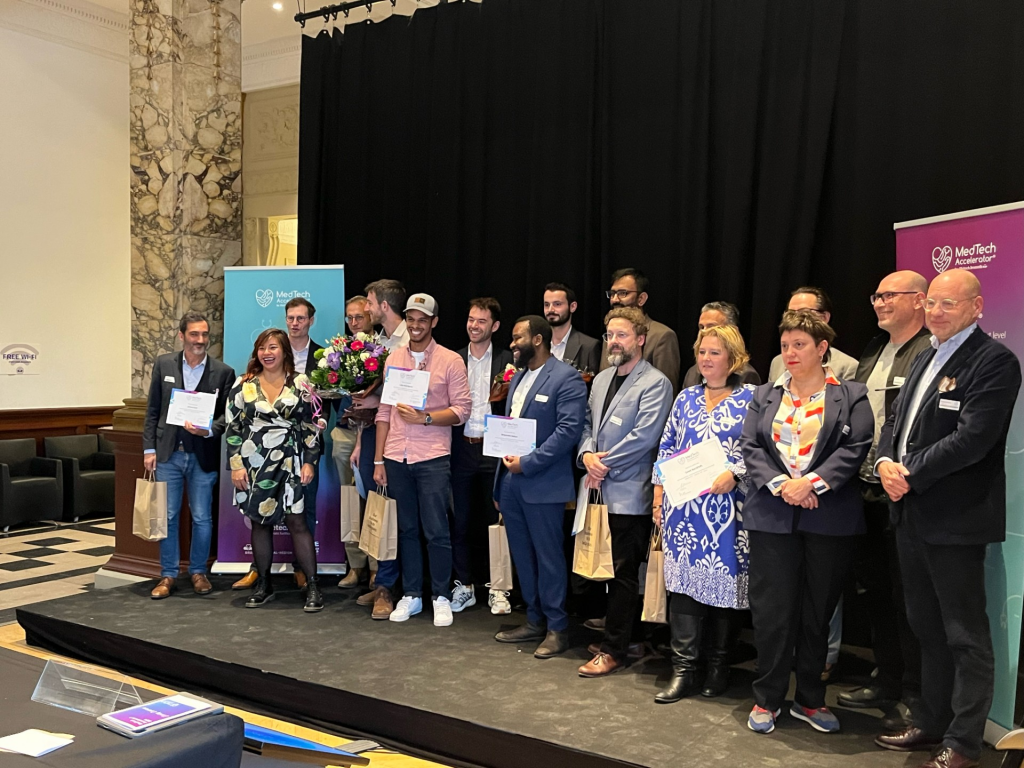
Some extra infomation can be found here.
- https://www.linkedin.com/posts/lifetech-brussels_medtechaccelerator-juryprize-publicprize-activity-7250177652748169216-x5-_?utm_source=share&utm_medium=member_desktop
- https://lifetech.brussels/en/medtech-accelerator/
- https://lifetech.brussels/en/innovation-in-progress/
The introductory movies for the projects:
Benyameen:
Pieter:
Redona Brahimetaj en Elena Botti hebben de best paper award gewonnen op het IWOAR 2025 congress met hun paper “Topological Versus Spatiotemporal Gait Parameters for Fall Risk Detection with IMU Sensors” (full author list: Redona Brahimetaj, Elena Botti, Ivan Bautmans, Eva Swinnen, Bart Jansen)
